SAGE

Scalable Agentic Grounded Evaluation for Crop Disease Diagnosis

1Iowa State University, USA 2New York University, USA

*Equal contribution (first authors). †Corresponding author: soumiks@iastate.edu

~839K
plant disease images
335
crops
1,251
disease classes
+16.2 pp
average accuracy gain from symptom knowledge
Method

System overview

SAGE system overview: curation pipeline and agentic evaluation

Curation (top): a source-cited disease KB (335 crops, 1,251 diseases) and an image corpus (~839K images) are assembled in parallel; expert audit and dedupe gate both tracks before image filtering tags every image with its anatomical context. Agentic evaluation (bottom): a VLM agent observes the affected organ, narrows candidates via the anatomical index, consults KB symptoms, and sequentially compares reference images in an open-ended loop bounded by reference budget k — producing a prediction with a step-by-step reasoning trace.

In the field

SAGE on the road

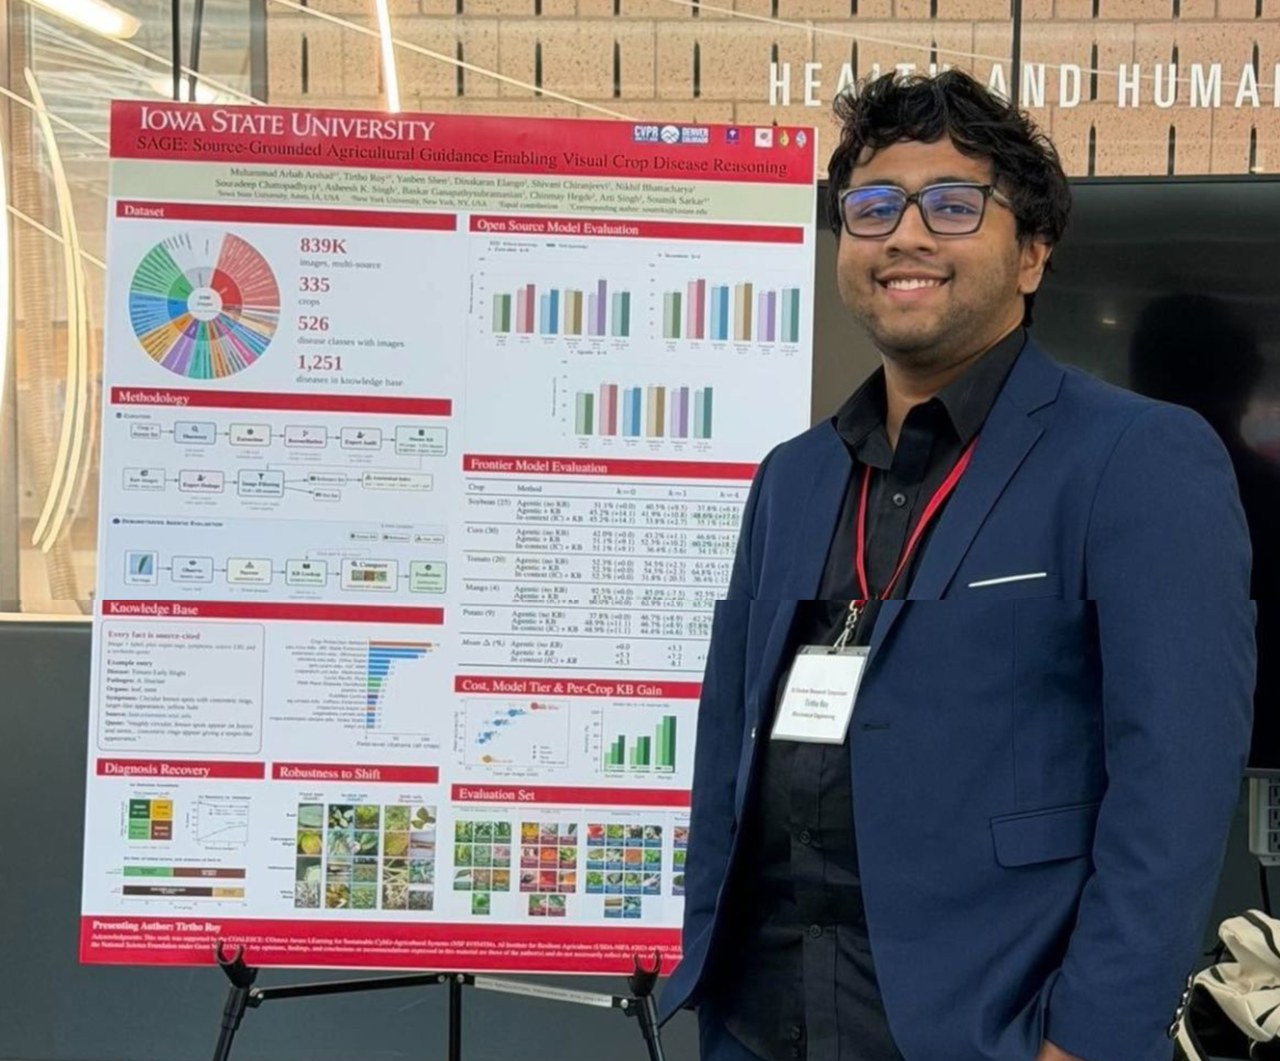
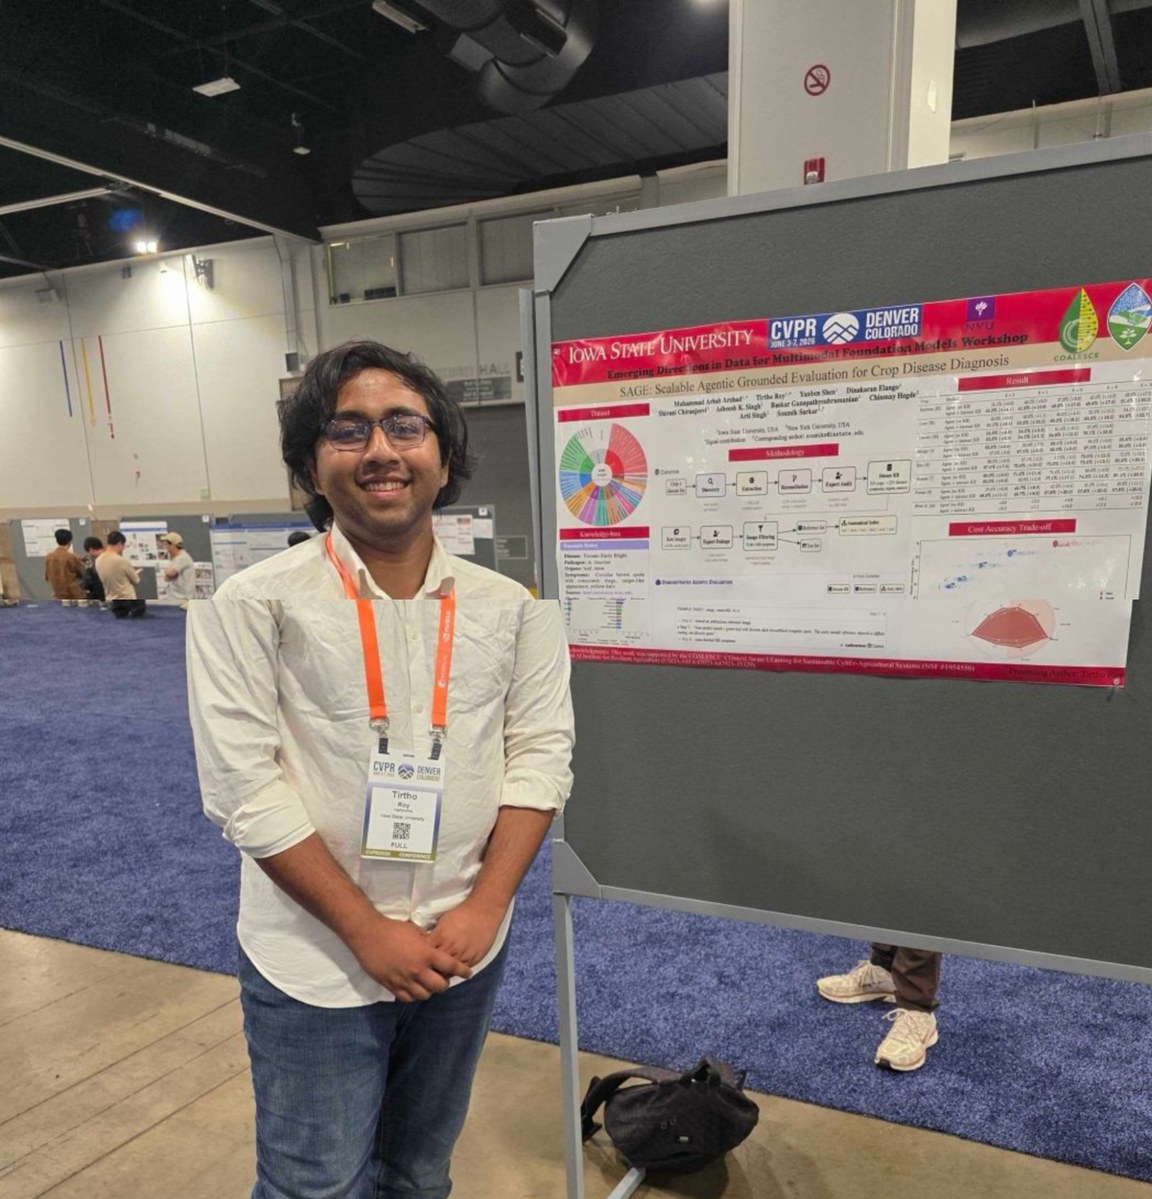
Tirtho Roy with the SAGE poster at the CVPR 2026 DataMFM Workshop in Denver
CVPR 2026 · Denver
DataMFM Workshop poster (non-archival track)
Tirtho Roy with the SAGE poster at the Iowa State University AI Student Research Symposium
Iowa State University · D4 NRT
AI Student Research Symposium poster
Tirtho Roy presents SAGE’s source-grounded knowledge base.
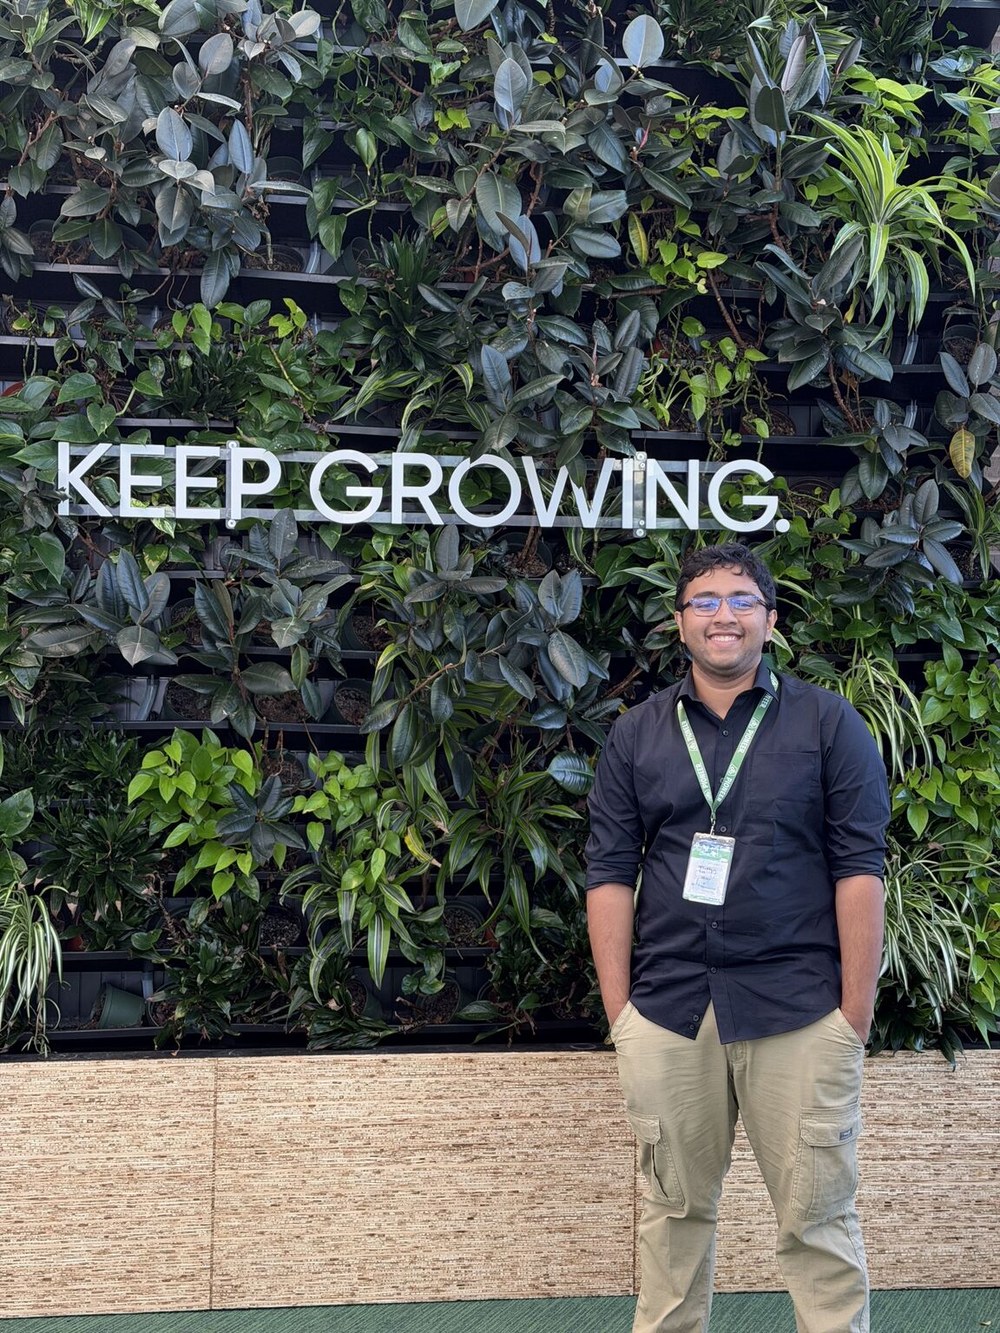
Tirtho Roy in front of the Keep Growing living wall at the Corteva Agriscience New Frontiers 2026 conference
Corteva Agriscience · 2026
New Frontiers conference
Tirtho Roy at New Frontiers, on the past, present and future of crop innovation.
Paper

Abstract

Accurate diagnosis of plant diseases is vital for food security worldwide. Since large-scale curated datasets for plant pathologies are scarce, training disease detection models that generalize across crops and field conditions remains hard. We compile the largest plant disease image dataset to date (~839K images, 335 crops, 1,251 disease classes), built for training-free prediction by visual agents. A scalable automated pipeline produces source-grounded symptom descriptions in which every fact ties to a verbatim web quote. Domain experts sanity-check sampled crops and reconcile disease-name variants across sources. As a baseline, we demonstrate an autonomous reasoning agent that identifies the anatomical context, narrows candidates using symptom knowledge, and sequentially compares reference images, producing a full, explainable reasoning trace. Adding symptom knowledge improves accuracy by 16.2 percentage points on average at full reference budget, with consistent gains across all four evaluation crops. We anticipate that the agentic baselines that we establish will benefit directly from future improvements in foundation model capabilities without retraining.

Contributions

What SAGE adds

Multi-crop image dataset

Spanning 335 crops and 1,251 disease classes (~839K images), assembled from established benchmarks, expert-curated collections, and community sources, with multi-organ coverage (leaf, stem, root, seed, ear, head).

Source-first disease registry pipeline

That, given a crop name, automatically produces structured symptom knowledge with per-field provenance: every fact traces back to a specific web source with a verbatim supporting quote.

Training-free agentic diagnostic pipeline

In which each prediction is made by an autonomous reasoning agent that produces an explainable, human-readable reasoning trace showing which references were examined and why.

Systematic evaluation

Across four crops of varying difficulty (Soybean, Corn, Tomato, Mango), multiple reference budgets (k = 0, 1, 4, 8), KB sources, and model tiers (Haiku, Sonnet, Opus).

Dataset

Dataset distribution

SAGE dataset distribution sunburst

Distribution of ~839K images across 335 crops and 1,251 disease classes. Each disease is paired with structured, source-cited symptom knowledge: organ tags, symptom descriptions, source URLs, and verbatim supporting quotes — not just an image and a label.

Every disease class comes with source-cited symptom knowledge, not only an image and a label.
Knowledge base

Where the symptom knowledge comes from

KB source distribution

Sources backing the disease registry across 10 released crops. Left: per-crop field-level citations stacked by source category. Right: top 15 cited domains. The pipeline draws predominantly from US land-grant extension publications, complemented by international compendia (CABI, Lucid Pacific Pests, PNW Plant Disease Handbook), peer-reviewed journals, and the multi-university Crop Protection Network.

Most facts trace back to US land-grant extension publications.
Results

Main results: accuracy vs. reference budget

Accuracy vs reference budget k

Diagnostic accuracy as a function of reference budget k across four crops of varying difficulty: Soybean (25 classes), Corn (30 classes), Tomato (20 classes), and Mango (4 classes). Each panel shows the agent without KB (blue) and with internet KB (red). Adding the KB consistently lifts accuracy, with the largest gains at low k — symptom descriptions and the anatomical index guide the agent to the most relevant references first.

The knowledge base lifts accuracy on every crop, most of all at low reference budgets.
Per crop

Per-crop KB effect at a glance

Per-crop accuracy split radar across reference budgets

Per-crop accuracy across reference budgets. The right semicircle shows accuracy with internet KB; the left shows the matched no-KB condition. Concentric polygons (light to dark) correspond to k = 0, 1, 4, 8. Right-side bulges across Soybean, Corn, and Tomato indicate consistent KB benefit; Mango is saturated and roughly symmetric.

Soybean, Corn and Tomato gain from the KB; Mango is already saturated.
Cost

Cost × accuracy across model tiers

Cost vs accuracy across model tiers and reference budgets

Cost-accuracy tradeoff (mean accuracy across all four crops, internet KB). Small dots show individual per-image API costs; large bubbles show aggregate means with bubble size proportional to reference budget k. Increasing k improves accuracy at growing cost with diminishing returns past k=8. Model quality is the single most impactful factor: the system gets better automatically as foundation models improve, with no retraining.

A stronger foundation model is the biggest lever, and it needs no retraining.
Error analysis

What the KB actually fixes

Soybean confusion matrix, baseline
31.1%

Baseline (Sonnet, k=0, no KB): 31.1%. Sudden-death-syndrome is heavily over-predicted (14 false positives), absorbing predictions from many other classes.

Soybean confusion matrix, full pipeline
48.6%

Full pipeline (Sonnet, k=8, internet KB): 48.6%. The over-predicted column is markedly reduced as the agent uses KB symptoms and reference comparisons to distinguish visually similar diseases.

Expert audit

Experts validate the knowledge base

Expert agronomist verdicts on KB-sourced claims

Expert agronomist verdicts on KB-sourced claims across soybean, mango, and corn. Every field carries per-field provenance — the extracted value, a source URL, and a verbatim supporting quote. Agreement ranges from 69% to 91%, with disagreement at or below 17%.

Agronomists agree with 69–91% of KB claims, and disagree with at most 17%.
Cite

BibTeX

@inproceedings{arshad2026sage,
  title     = {SAGE: Scalable Agentic Grounded Evaluation for Crop Disease Diagnosis},
  author    = {Arshad, Muhammad Arbab and Roy, Tirtho and Shen, Yanben and Elango, Dinakaran and Chiranjeevi, Shivani and Singh, Asheesh K. and Ganapathysubramanian, Baskar and Hegde, Chinmay and Singh, Arti and Sarkar, Soumik},
  booktitle = {CVPR 2026 Workshop on Emerging Directions in Data for Multimodal Foundation Models},
  note      = {Non-archival track},
  year      = {2026},
  url       = {https://arxiv.org/abs/2605.09768}
}
People

Team

Acknowledgments

Funding

This work was supported by the COALESCE: COntext Aware LEarning for Sustainable CybEr-Agricultural Systems (NSF #1954556), AI Institute for Resilient Agriculture (USDA-NIFA #2021-67021-35329).